Beyond Autocomplete: Orchestrating Multi-Agent Coding Fleets in Enterprise Repositories
Published: 06 November 2026
The adoption of generative AI in software engineering has rapidly progressed beyond single-token tab completions and conversational chatbots. While first-generation developer assistants provided productivity boosts by synthesizing boilerplate functions and suggesting regex syntax, enterprise software development demands far more than local autocomplete. Real-world development is inherently collaborative, multi-file, and context-dependent, involving systemic architectural constraints, continuous integration gates, and complex dependency graphs.
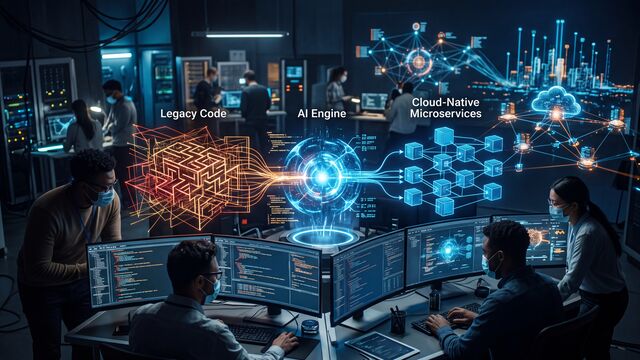
To unlock the next frontier of engineering velocity, forward-thinking organizations are orchestrating multi-agent coding fleets. Rather than relying on a developer to manually prompt, copy, and stitch together code snippets across disparate files, multi-agent frameworks deploy specialized, autonomous agents that coordinate across repositories. These fleets break complex engineering epics into discrete, manageable subtasks—independently reading documentation, executing terminal commands, modifying multi-file architectures, and validating code against continuous integration suites.
The Structural Limits of Inline Autocomplete
Inline code suggestions provide undeniable value during routine programming, but they fail to address the core bottlenecks of enterprise software delivery. Autocomplete assistants operate on limited, localized context windows, primarily analyzing the currently open buffer and immediate neighbor files.
This localized scope introduces critical limitations:
- Lack of Systemic Context: Single-line autocomplete models cannot evaluate how a database migration in an order management service impacts serialization logic in an inventory consumer three repositories away.
- Absence of Planning and Reasoning: Autocomplete is fundamentally predictive rather than deliberative. It cannot decompose a complex refactoring task into logical execution milestones, identify potential race conditions, or adapt to compiler diagnostics.
- Human Burden of Verification: Developers are forced to constantly context-switch, acting as human parsers for hundreds of auto-suggested snippets. This cognitive load often leads to rubber-stamping code reviews and subtle regressions.
The Multi-Agent Coding Paradigm
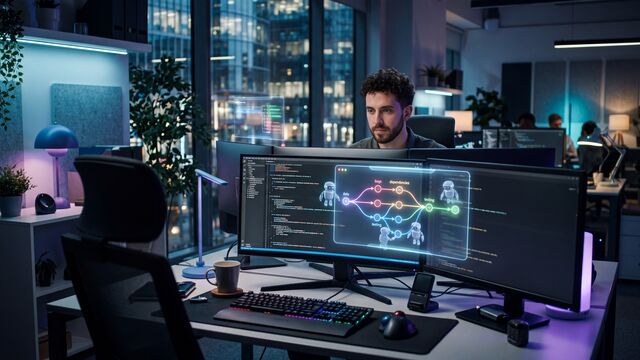
Moving beyond autocomplete requires transitioning from passive suggestion engines to active agentic swarms. In an autonomous multi-agent architecture, tasks are distributed among specialized artificial intelligence agents, each with dedicated roles, system prompts, and sandboxed execution privileges.
A production-grade multi-agent coding workflow typically involves three primary specialized agents:
- The Architect Agent: Ingests feature specifications, searches the repository knowledge graph, and maps out a deterministic implementation plan. It defines file boundaries, interface contracts, and testing criteria before any code is generated.
- The Implementation Agent: Operates inside an isolated container runtime, modifying code across multiple files according to the architectural specification. It reads repository files, runs localized builds, and iterates based on compiler warnings.
- The Verification Agent: Executes unit test suites, performs static security analysis, checks styling standards, and generates comprehensive pull request documentation detailing changes, trade-offs, and verification results.
By decoupling planning, implementation, and verification, multi-agent systems dramatically reduce hallucination rates and ensure that synthetic code adheres strictly to established system design patterns.
Sandboxed Runtimes and Context Orchestration
Executing autonomous code generation across enterprise repositories requires enterprise-grade sandboxing and state management. Granting AI agents direct access to developer machines or production networks introduces severe security and operational risks.
Leading organizations implement ephemeral, containerized development environments—such as isolated Docker micro-VMs or secure devcontainers—where agents can safely execute shell commands, install dependencies, and run integration test suites without risking host system corruption.
Simultaneously, context orchestration must evolve beyond naive vector retrieval. Multi-agent fleets leverage semantic Abstract Syntax Tree (AST) analyzers and code knowledge graphs to extract structural symbol dependencies, call hierarchies, and API contracts. This structured context ensures agents receive precise, deterministic architectural metadata without overwhelming token limits.
Preventing Architectural Fragmentation
Without rigorous governance, deploying autonomous coding agents can inadvertently accelerate technical debt. If agents generate idiosyncratic abstractions or introduce redundant utility libraries across separate feature branches, the enterprise codebase risks rapid architectural fragmentation.
To maintain repository integrity, engineering leaders must enforce automated guardrails:
- Repository-Specific Golden Paths: Agents must be constrained by machine-readable architectural blueprints (e.g., modular boundaries, naming conventions, and approved third-party dependencies).
- Deterministic Evaluation Gates: Every synthetic code iteration must pass automated linting, type-checking, and regression test suites before code reaches human review.
- Continuous Agent Benchmarking: Tracking agent task completion rates, regression frequency, and review rework provides engineering leaders with empirical insight into agent performance.
Accelerating Agentic Engineering with Aqon
Transitioning your development organization from basic AI autocomplete tools to an orchestrated multi-agent development pipeline requires deep expertise in container isolation, semantic code indexing, and continuous delivery engineering.
Aqon provides the strategic consulting and hands-on systems architecture needed to integrate autonomous coding agents safely into your enterprise software lifecycle. Our technical consultants work alongside your platform and software engineering teams to configure secure sandboxed runtimes, design multi-agent coordination pipelines, and establish governance frameworks that protect repository stability. With Aqon, your organization can achieve breakthrough software delivery speeds while maintaining uncompromising architectural rigor.
Are you ready to move beyond inline autocomplete and scale autonomous engineering pipelines? Contact Aqon today to schedule a consultation with our AI software architecture specialists.
Next Up: From Reactive to Predictive: Utilizing Real-Time Log Telemetry to Prevent Cloud Cost Spikes
Latest Articles